Project notes / Cynthia Owolabi
SourceDesk
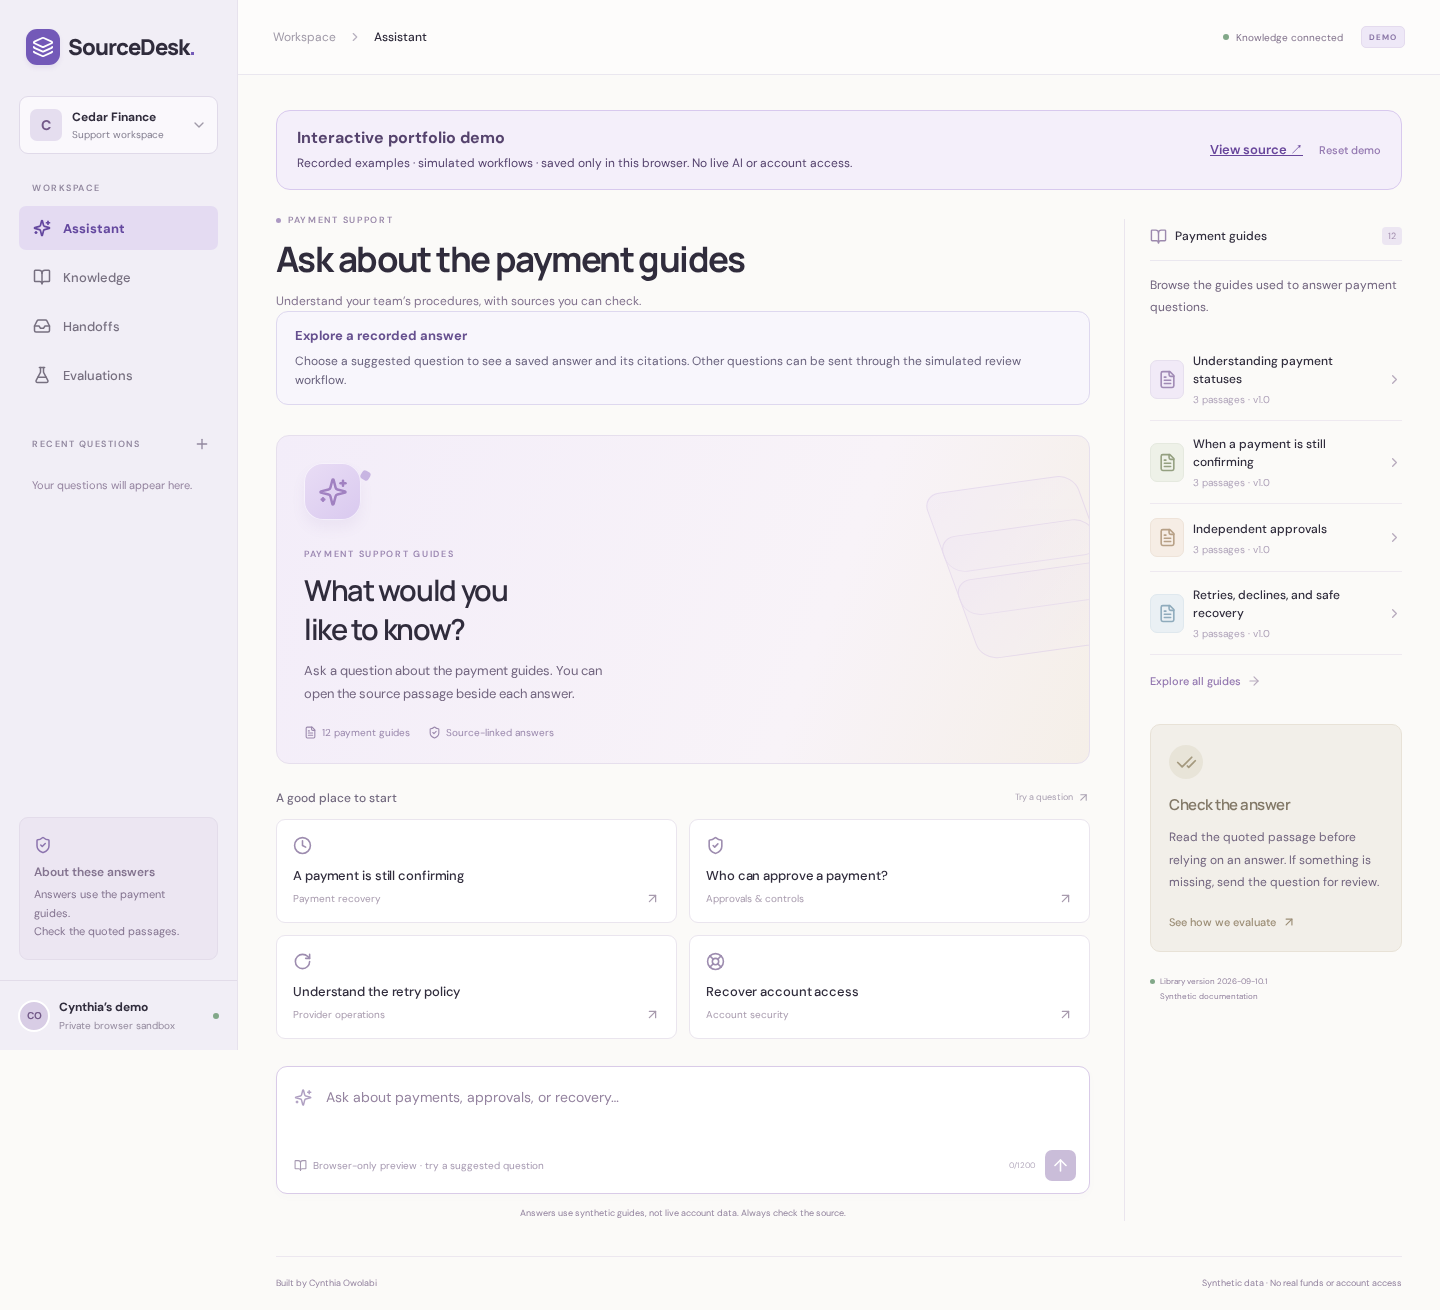
An early SourceDesk answer implied it knew what had happened to someone’s payment. It only had documentation. That mistake shaped how the app handles account questions and how I reviewed the generated answers.
Answering from the guides
SourceDesk searches 12 fictional payment guides. The default mode returns matching passages directly. With GPT and pgvector enabled, it writes an answer using retrieved passages and includes quotes you can check. Account-specific questions and questions outside the guides' coverage go to review.
Keeping citations tied to the answer
Each search index records which documents and embedding model it was built from. A new index becomes active only after indexing finishes. Saved answers retain a copy of their source passages through later guide edits.
For this small set of guides, I used exact vector search. The app checks that each quoted passage exists in the retrieved source. That catches invented quotations. Reviewers still need to check whether the quoted passage supports the model's interpretation.
What the first tests caught
The first run passed 38 of 40 questions. It missed a paraphrased role name and answered a question about someone’s account with general documentation. I fixed the normalization and scope checks, then reran the same suite: 40 of 40 passed.
A separate live test caught the account-specific wording mentioned above. I changed the prompt to describe the documentation's conditions explicitly.
Try an account question
In the demo, ask a documentation question, inspect its quoted source, then ask about your own missing funds. Compare the answer and handoff paths. The hosted preview runs recorded synthetic responses in your browser.
Reading the test results
- All 40 development questions pass after fixes. I saw the full set during development, including the subset originally called “holdout,” so these results track regression performance on the development set.
- The live test indexed 30 passages and passed five smoke cases. It confirms that the API and retrieval path work together. Five cases are too few to judge general answer quality.
- Reviewing the answers caught a wording problem that the automated checks missed. Independent review of claim support remains outstanding.
Methodology and failure record · Live smoke outputs · Installation
npm ci
npm run evaluate
This runs the local regression suite.
What still needs testing
The app has only been tested with this small collection of guides. The next useful evaluation would use questions written independently of the implementation, with people checking whether each answer follows from its sources and whether a handoff was needed. That work is still outstanding.